AI
backpropagation
the chain rule computing every weight's gradient in one backward pass
Source board
This definition comes from the board below. Open it to see the term in context.
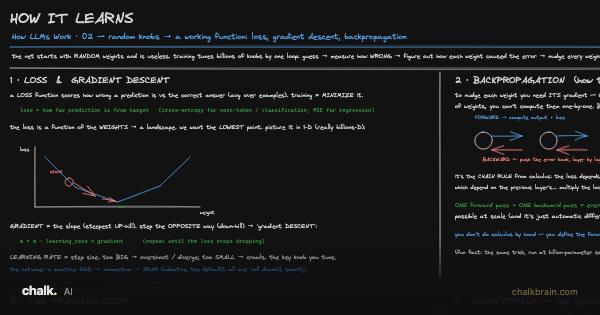 How It LearnsAI
More terms from this board
- automatic differentiationthe framework doing it for you
- batch / mini-batcha subset processed per step
- convergencethe loss stops dropping
- epochone pass over all data
- generalizationworking on unseen data (the goal)
- gradientslope of the loss w.r.t. the weights
- gradient descentstep downhill to reduce loss
- learning ratestep size
- loss / cost functionhow wrong the prediction is (cross-entropy, MSE)
- optimizer (SGD/Adam)the downhill-stepping algorithm
- overfittingmemorizing train data, failing on new
- parameters/weightswhat's being tuned
- regularizationdropout / weight decay to prevent overfitting
- stepone weight update
- validation set / early stoppingmonitor & stop in time