Data Systems
bounded input
finite dataset, so the job finishes
Source board
This definition comes from the board below. Open it to see the term in context.
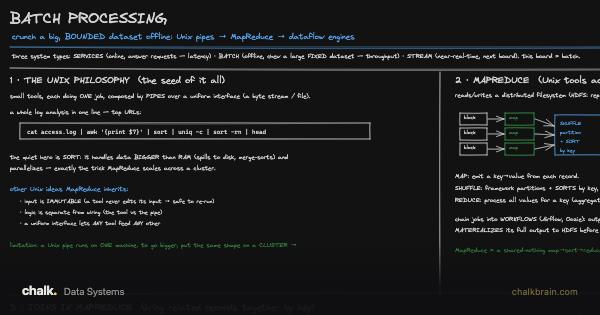 Batch ProcessingData Systems
More terms from this board
- batch vs service vs streamoffline bulk / online requests / near-real-time
- dataflow engine (Spark/Flink)one DAG, in-memory, no forced materialization
- distributed filesystem (HDFS)replicated blocks across shared-nothing nodes
- map-side (broadcast hash) joinsmall table in every mapper's RAM
- MapReducemap → shuffle(sort) → reduce over a cluster
- materializationwriting full intermediate output to disk
- RDD / lineagerecompute lost data from its recipe
- reduce-side (sort-merge) joinjoin in the reducer after a shuffle
- saltingsplit a hot key
- shufflepartition + sort by key
- Unix pipestream one tool's output into the next
- workflow/DAGchained jobs