AI
context window
max tokens the model sees at once
Source board
This definition comes from the board below. Open it to see the term in context.
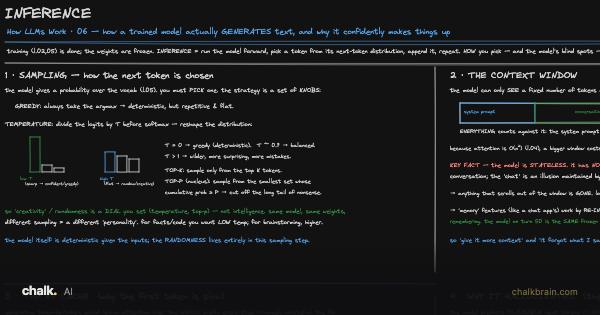 InferenceAI
More terms from this board
- greedyalways take the top token
- groundingRAG/tools to tie answers to real sources
- hallucinationconfident, fluent, but false output
- inferencegenerating text from the trained model
- KV cachestored Keys/Values of past tokens (speeds generation)
- prefill vs decodeprocess the prompt vs generate token-by-token
- samplingpicking the next token from the distribution
- statelessno memory between calls (history is re-sent)
- temperaturerandomness dial (0 = deterministic)
- the KV cache grows with contextthe memory cost of long context
- throughputtokens/sec
- top-k / top-p (nucleus)sample only from the top tokens / the top cumulative mass
- TTFTtime to first token