AI
self-attention
each token attends to the others in its own sequence
Source board
This definition comes from the board below. Open it to see the term in context.
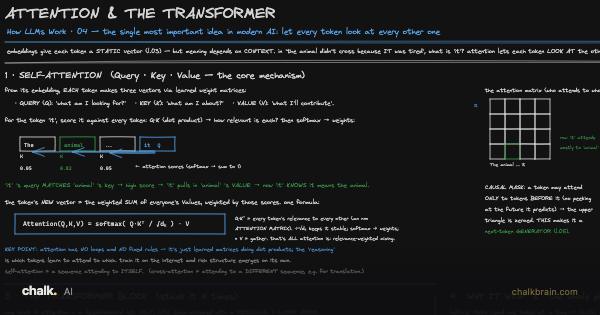 Attention and the TransformerAI
More terms from this board
- attention matrixn×n who-attends-to-whom
- causal maskcan only attend to earlier tokens (for generation)
- cross-attentionattend to another sequence
- feed-forward (FFN/MLP)the per-token 'thinking' layer
- layer normstabilizes activations
- multi-headparallel attentions capturing different relations
- O(n²)attention's cost in sequence length (the context bottleneck)
- Query/Key/Value'what I seek / what I offer / what I give'
- residual connectionadd the input back (deep-net enabler)
- scaled dot-product attentionsoftmax(QKᵀ/√d)V
- stack of N blocksthe depth of the model
- transformer blockattention + FFN + residual + LayerNorm