AI
instruction tuning
SFT across many task types
Source board
This definition comes from the board below. Open it to see the term in context.
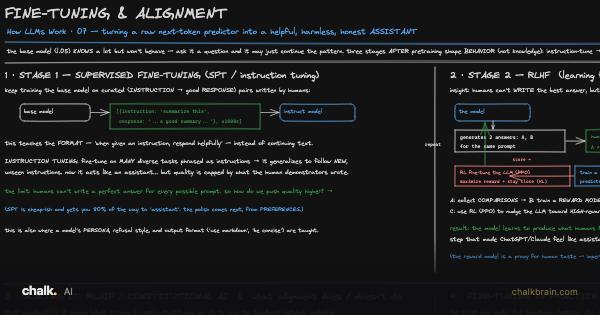 Fine-tuning and AlignmentAI
More terms from this board
- alignment taxcapability lost to safety
- base vs aligned modelraw predictor vs assistant
- Constitutional AIself-critique against written principles (Anthropic)
- fine-tuningextra training on a specific task
- HHHhelpful, harmless, honest
- KL penaltystay close to the original model
- LoRAcheap parameter-efficient fine-tuning (small adapters)
- PPOthe RL algorithm
- reward hackingover-optimizing the proxy
- reward modelpredicts human preference score
- RLAIFfeedback from an AI instead of humans
- RLHFreinforcement learning from human feedback
- SFTsupervised fine-tuning on instruction→response pairs