The LoRA rank
Fine-tuning a 7B model with LoRA trains a small correction beside the frozen weights. How big should the correction be?
A 7B model sits frozen, all 7 billion numbers, and a thin correction trains beside each chosen attention grid. One dial sets how big each correction is. The panels show the trainable numbers, the memory to train against a full fine-tune's 112 GB, and an illustrative quality curve. Cost climbs in a straight line; quality flattens past rank 16.
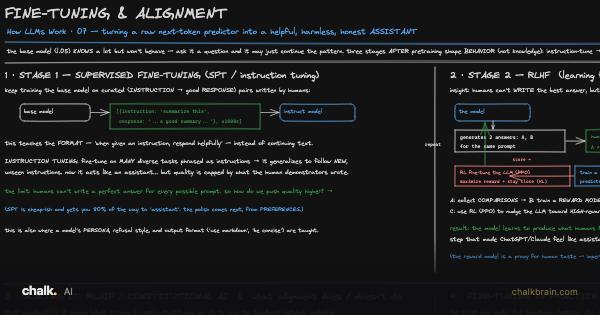 Board: Fine-tuning and Alignment →
On a narrow screen the three panels stack. The controls stay above them, and the table scrolls sideways.
try this Drag How big each correction is from r = 1 to r = 256 and watch Memory to train climb while Quality stalls.
Included with a plan
This lab is included with a plan. The first three lessons of every track are free, with their boards and videos. A plan unlocks every lesson, board, video, lab and paper for one price.
see also LoRA: Low-Rank Adaptation of Large Language Models and Training language models to follow instructions with human feedback in Papers.