Many experts, one router
Doubling the experts doubles what the model knows and costs nothing per token. So what does it cost?
A router reads each token and sends it to a couple of specialists out of a much larger bench. Three numbers sit side by side: everything the model knows, the small slice it actually computes with, and the memory that has to hold all of it anyway. Add experts and watch which of the three stays still.
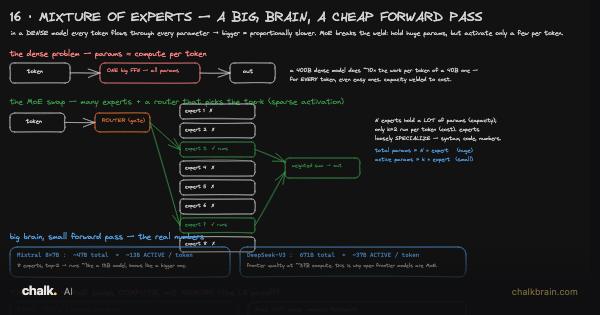 Board: Many Experts One Router →
Three panels stack on a narrow screen; the per-expert bars keep their own width and scroll.
try this Drag Experts you hold to the right and watch What it computes refuse to move while the other two panels climb.
Included with a plan
This lab is included with a plan. The first three lessons of every track are free, with their boards and videos. A plan unlocks every lesson, board, video, lab and paper for one price.
see also The Bitter Lesson and Training Compute-Optimal Large Language Models in Papers.