Mixture of Experts (a big brain with a cheap forward pass)
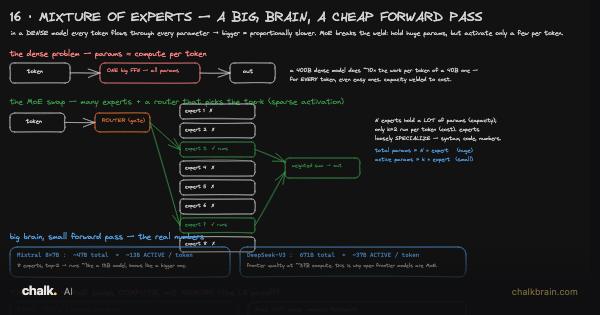
Many Experts One Router, from the How LLMs Work track. The architecture behind Mixtral, DeepSeek-V3 and Qwen-MoE, and the story of how a 1991 paper about vowel sounds became the way frontier models are built. The “forward pass” in the title is one word’s trip through the machine. The lab lets you change how many experts a word visits and watch work and memory come apart.
Before you start. A language model is a pile of numbers, called its weights or its dials; the formal word is parameters. There are billions of them, and the model runs on a graphics card. The idea from Inference at Scale (why an LLM is fast, and cheap): to write one word the card must read every one of those numbers out of its own memory, and that reading takes longer than the arithmetic it does with them. So the size of the pile is what you wait on. You also need, from Attention & the Transformer, that a layer is two steps: attention, where every word glances at every other, then a plain row of dials each word passes through alone. That second step is the feed-forward network. It holds nearly all the numbers, and it is what this lesson splits up.