Index

Fine-tuning & Alignment
Fine-tuning and Alignment
Fine-tuning and Alignment · Open board

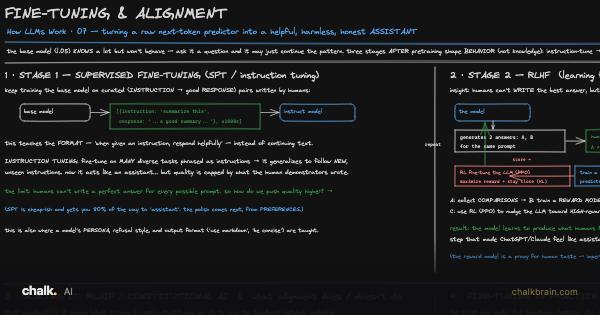
The How LLMs Work board that picks up the split left open by From Transformer to LLM: a machine that predicts the next word, and a thing that answers you. How the first became the second is mostly a story about people pointing at the better of two answers.

Before you start. You need one fact from From Transformer to LLM: training a language model means hiding the next word in a mountain of text and turning the model’s dials until it guesses well. Nothing here changes that machine. It changes only what the machine is rewarded for doing with it.

Continue reading with a plan

The first three lessons of every track are free. This lesson is included with a plan, which unlocks every lesson, board, video, lab and paper for one price.

View plans →Already a member? Sign in

Lab

Fine-tuning a 7B model with LoRA trains a small correction beside the frozen weights. How big should the correction be?

Drag How big each correction is from r = 1 to r = 256 and watch Memory to train climb while Quality stalls.

Open The LoRA rank →

Related paper

Review AI →

Saved in this browser, and to your account when you sign in.