Attention by Hand
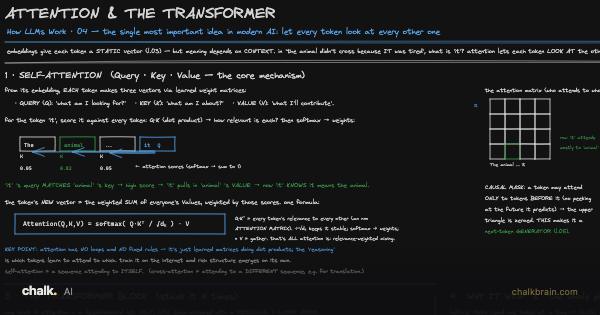
The Attention and the Transformer board draws each word looking back at the words before it. This lesson builds that look by hand, then trains it: the fourth of six lessons that end with a small GPT built from scratch. A GPT is the kind of model behind ChatGPT: it writes text one piece at a time, each time guessing what comes next.
Before you start. A weight is one adjustable number inside a model, and training nudges every weight to make the loss smaller (Autograd by Hand). The loss is one number for how wrong the model’s guesses were, and lower is better. In The MLP Language Model a model read the last eight characters of a returns-desk reply (a short customer-service reply about a returned order) and guessed the next one. That model was an MLP, a multilayer perceptron: layers of neurons stacked one after another. From The Maths Floor, Part 2: Probability, Softmax and Temperature: softmax turns a list of scores into shares that add up to 1. From Vectors, Dot Products and Matrix Multiply: multiply two lists of numbers pair by pair and add the products, and you get one number that is big when the lists match. From Attention & the Transformer: attention lets each word take a share of its meaning from each word before it.