Index

Module 02 · AIFrom a model to an app

Inference (sampling, context, KV cache, hallucination)
Inference
Inference · Open board

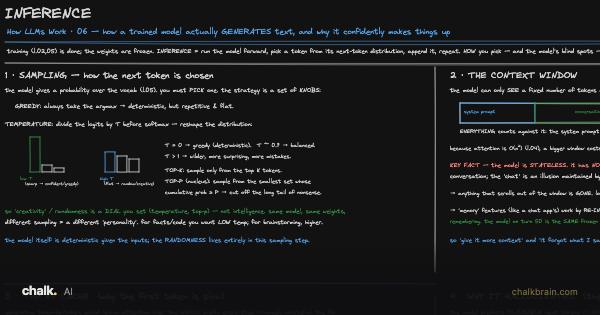
The Inference board of the How LLMs Work track. Training is over and the weights will never change again. This is what happens in the seconds after you hit enter.

Before you start. You need to know that the model is a huge pile of fixed numbers, its parameters (a 7-billion-parameter model is a pile of 7 billion of them), which scores every word that could come next; From Transformer to LLM is where that pile came from. It deals in tokens, chunks of roughly three quarters of a word, from Tokens & Embeddings. No maths beyond adding and dividing.

Continue reading with a plan

The first three lessons of every track are free. This lesson is included with a plan, which unlocks every lesson, board, video, lab and paper for one price.

View plans →Already a member? Sign in

Lab

One GPU, one chat, cores 99% idle. How many more chats fit before anything gets slower?

Drag Chats sharing one read of the weights to the right and watch operations per byte rise until The wall stops it.

Open The batch size dial →

The model has read 'The weather today is'. How often does it say something other than sunny?

Drag How hard the drum is shaken from T = 0.1 to 5 and watch Outside the top word climb.

Open The temperature dial →

Review AI →

Saved in this browser, and to your account when you sign in.