Constrained Decoding (the grammar holds the pen)
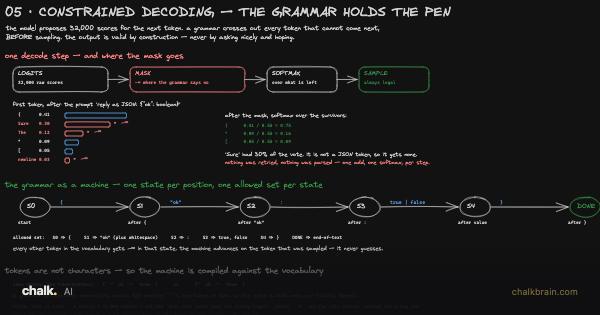
Serving LLMs. Prefill / Decode Split (two pools, one KV in flight) asked where a request’s compute runs. This board asks a different question: once the model is about to write its next word, what is it actually allowed to write? It draws one step with a mask wedged into it, the small machine a format turns into, and a ladder of four constraints ending in the one thing none of them can promise.
Before you start. This track is about serving large language models, and one of them writes its reply a token at a time, where a token is a word or a piece of one; this lesson says “word” for readability and the second half comes back to the difference. Every time the model is about to write another word, it scores every word it knows, turns that list of scores into odds and rolls dice on those odds. It never picks a word freely. It always picks one off that scored list. That step is called decoding, and an earlier lesson priced one of them at 39 milliseconds for a batch of 32 requests. This lesson never touches that price. It only touches which words the dice are allowed to land on. You should also know what a tool call is: a name and a required shape of arguments that the model fills in, first given to it in 2023.