Inference Engineering (serving an LLM is a systems problem)
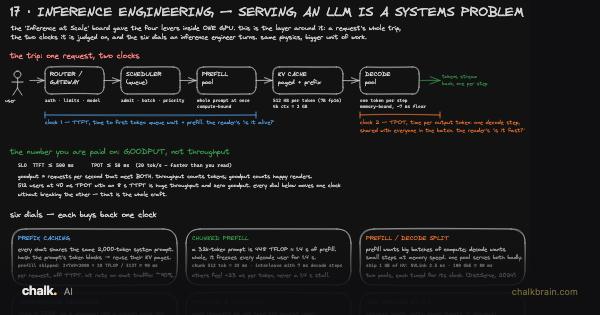
The board behind this lesson: one message’s whole trip through a fleet of machines, and the two clocks it’s judged on. Inference at Scale (why an LLM is fast, and cheap) made one GPU answer one request fast. This lesson is about what happens when a thousand requests hit that same pool of GPUs at once, and why some of those people feel it as fast while others feel the exact same server as slow.
Before you start. Inference at Scale (why an LLM is fast, and cheap) showed you how to make one GPU answer one request fast: handle several requests together in one go, shrink the model’s dials, page the model’s working notes instead of reserving a fixed slab for them, and guess ahead at the next few words before checking them. This lesson keeps every one of those tricks and asks what happens when a thousand people share that same GPU pool at once, each one noticing a different kind of “slow.”