Chunked Prefill (one long prompt must not freeze the room)
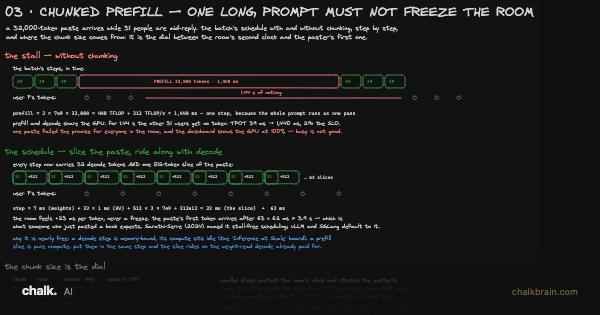
Serving LLMs, the third board. It draws the batch’s schedule twice: once when a long paste runs whole and freezes the room, once sliced into pieces that ride along with everyone else’s replies.
Before you start. The Two Clocks (TTFT, TPOT, and why goodput is the number) gave you the room: 32 people sharing one GPU, each getting a new token every 39 ms, a promise called TPOT that a busy GPU can still break. A token is a word or a piece of one, and producing one means pushing it through the model’s weights, the 7 billion numbers the model learned while it was trained. Prefix Caching (the same start, computed once) then showed the machine skip re-reading a system prompt it has already read once; this lesson is about the prompt it has never read before.