The MLP Language Model
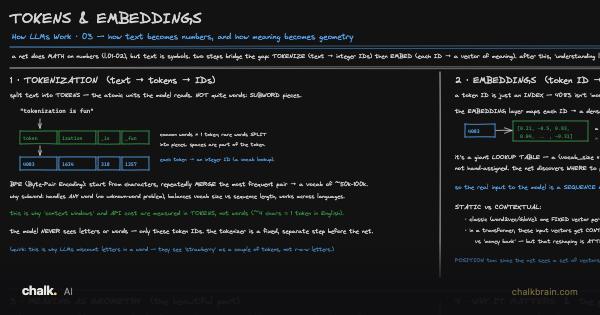
The Tokens and Embeddings board draws text turned into lists of numbers. This lesson learns one for every character: the third of six lessons that end with a small GPT built from scratch.
Before you start. A weight is one adjustable number inside a network; training nudges every weight, over and over, to shrink the loss, one number for how wrong the guesses were. Training finds, for every weight at once, which way to nudge it (Autograd by Hand builds the code that does this). In The Bigram Model a model read 3,000 returns-desk replies and guessed each next character from only the one before it, turning 51 scores (one per possible character) into chances with softmax; its loss on replies it never trained on was 1.97, where knowing nothing scores 3.93. From Tokens & Embeddings: an embedding is a short list of numbers that stands for one piece of text, kept as one row of a table and picked out by that piece’s id. From What a Neural Network Is: a hidden layer is a row of neurons between the input and the answer, each adding up its inputs times weights plus a bias, an extra adjustable number that shifts where the neuron fires. From Why the Loss Won't Go Down: the learning rate is how far each nudge goes, and the loss curve, the loss printed as training runs, shows whether it is right.