Prefill / Decode Split (two pools, one KV in flight)
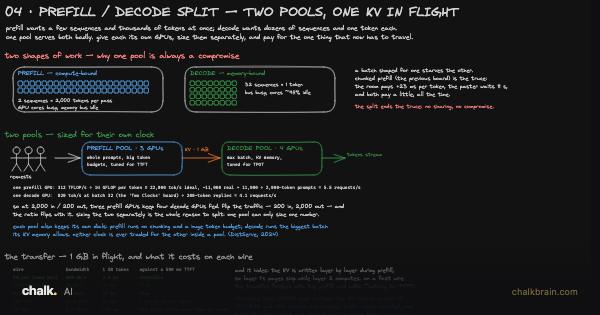
Serving LLMs. Chunked Prefill (one long prompt must not freeze the room) ended in a truce: one shared card, the long prompt sliced so it rides along with everyone else’s reply, everyone paying a little all the time. This board breaks the truce instead of managing it - reading and writing on two separate machines - and then prices the one bill that truce never had to pay: a gigabyte of notes crossing a wire between them.
Before you start. Chunked Prefill (one long prompt must not freeze the room) left you in a room where 32 people share one card. The card is a GPU: the chip built for doing the same arithmetic on millions of numbers at once. The whole model lives on it, and thirty-two people share one because a single pass through the model answers all thirty-two of them. The rest of this lesson just says card, and the diagrams say GPU; they are the same chip. A token - a word, or a piece of one - arrives for each of those people every 39 milliseconds. The card makes that token by pushing it through the model’s weights, the 7 billion numbers it learned during training. Reading a prompt for the first time, before any reply starts, is prefill; writing the reply afterward, one token at a time, is decode. Every token a conversation has already produced leaves behind notes about itself, its KV cache, that decode has to keep re-reading for every later token. K and V are for key and value: the two numbers the model keeps per token so it never has to read that token again. Moving that cache is exactly the new problem this lesson has.