Sampling and What Scale Buys
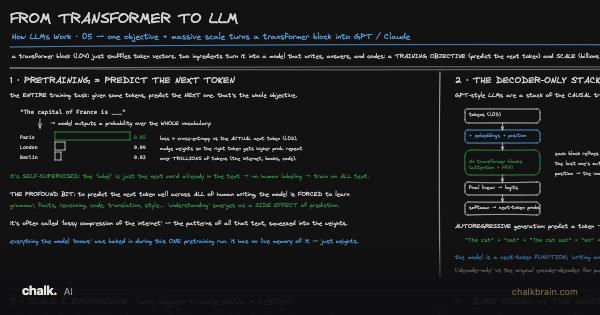
The From Transformer to LLM board draws the machine that fills in the next blank. This lesson makes the small one write, then counts the distance to a big one: the last of six lessons that build a small GPT from scratch.
Before you start. In The GPT Block you trained a small GPT, the kind of model built in the last two lessons, which writes one character at a time. Trained on 3,000 short returns-desk replies, it scores each of the 51 characters that could come next. From The Maths Floor, Part 2: Probability, Softmax and Temperature: softmax turns scores into chances that add up to 1. Sampling draws one outcome in proportion to its chance. Temperature divides every score first. From Tokens & Embeddings: a real model reads tokens, chunks of text about four characters long. A weight is one number inside the model. fp16 stores each weight in 2 bytes, so 7 billion weights take 14 GB. From The GPU (thousands of cores, and the memory that feeds them): an A100 is a GPU chip for AI work, and it reads its memory at 2 TB/s.