Evaluating Models (how do you know it’s good?)
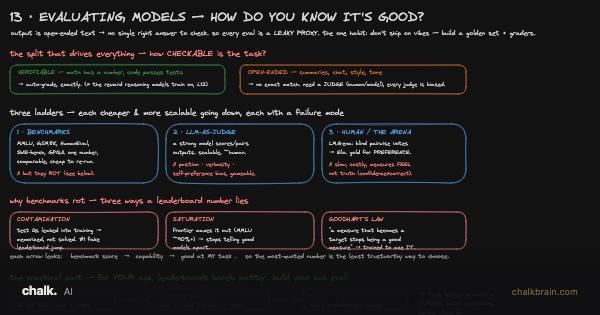
How Do You Know It’s Good?, on the How LLMs Work track. It closes the production trio: Inference at Scale (why an LLM is fast, and cheap) served the model, Reasoning & Test-Time Compute (why "thinking longer" works) taught it to think longer, and this one asks whether any of it is good. It is the story of how a field learned to set itself an exam, and of every way an exam lies.
Before you start. You need to know a language model writes open-ended text rather than picking one label from a list, which is what Inference (sampling, context, KV cache, hallucination) showed it doing one word at a time. The rest of the story is people, exams, and one score that fell thirteen points when the questions changed.