RAG (Retrieval-Augmented Generation)
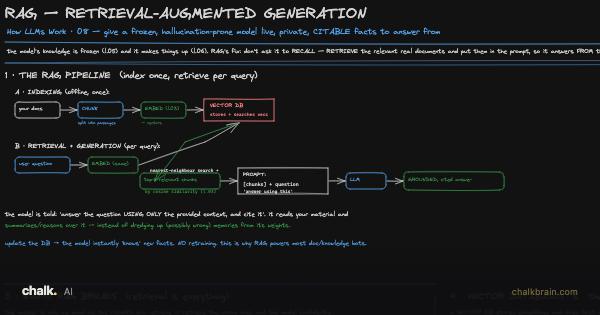
The RAG board from the How LLMs Work track. It draws a question going out to a library before it ever reaches the model. This lesson is the story of a lawyer who skipped that step, and of the paper that had already shown what to do instead.
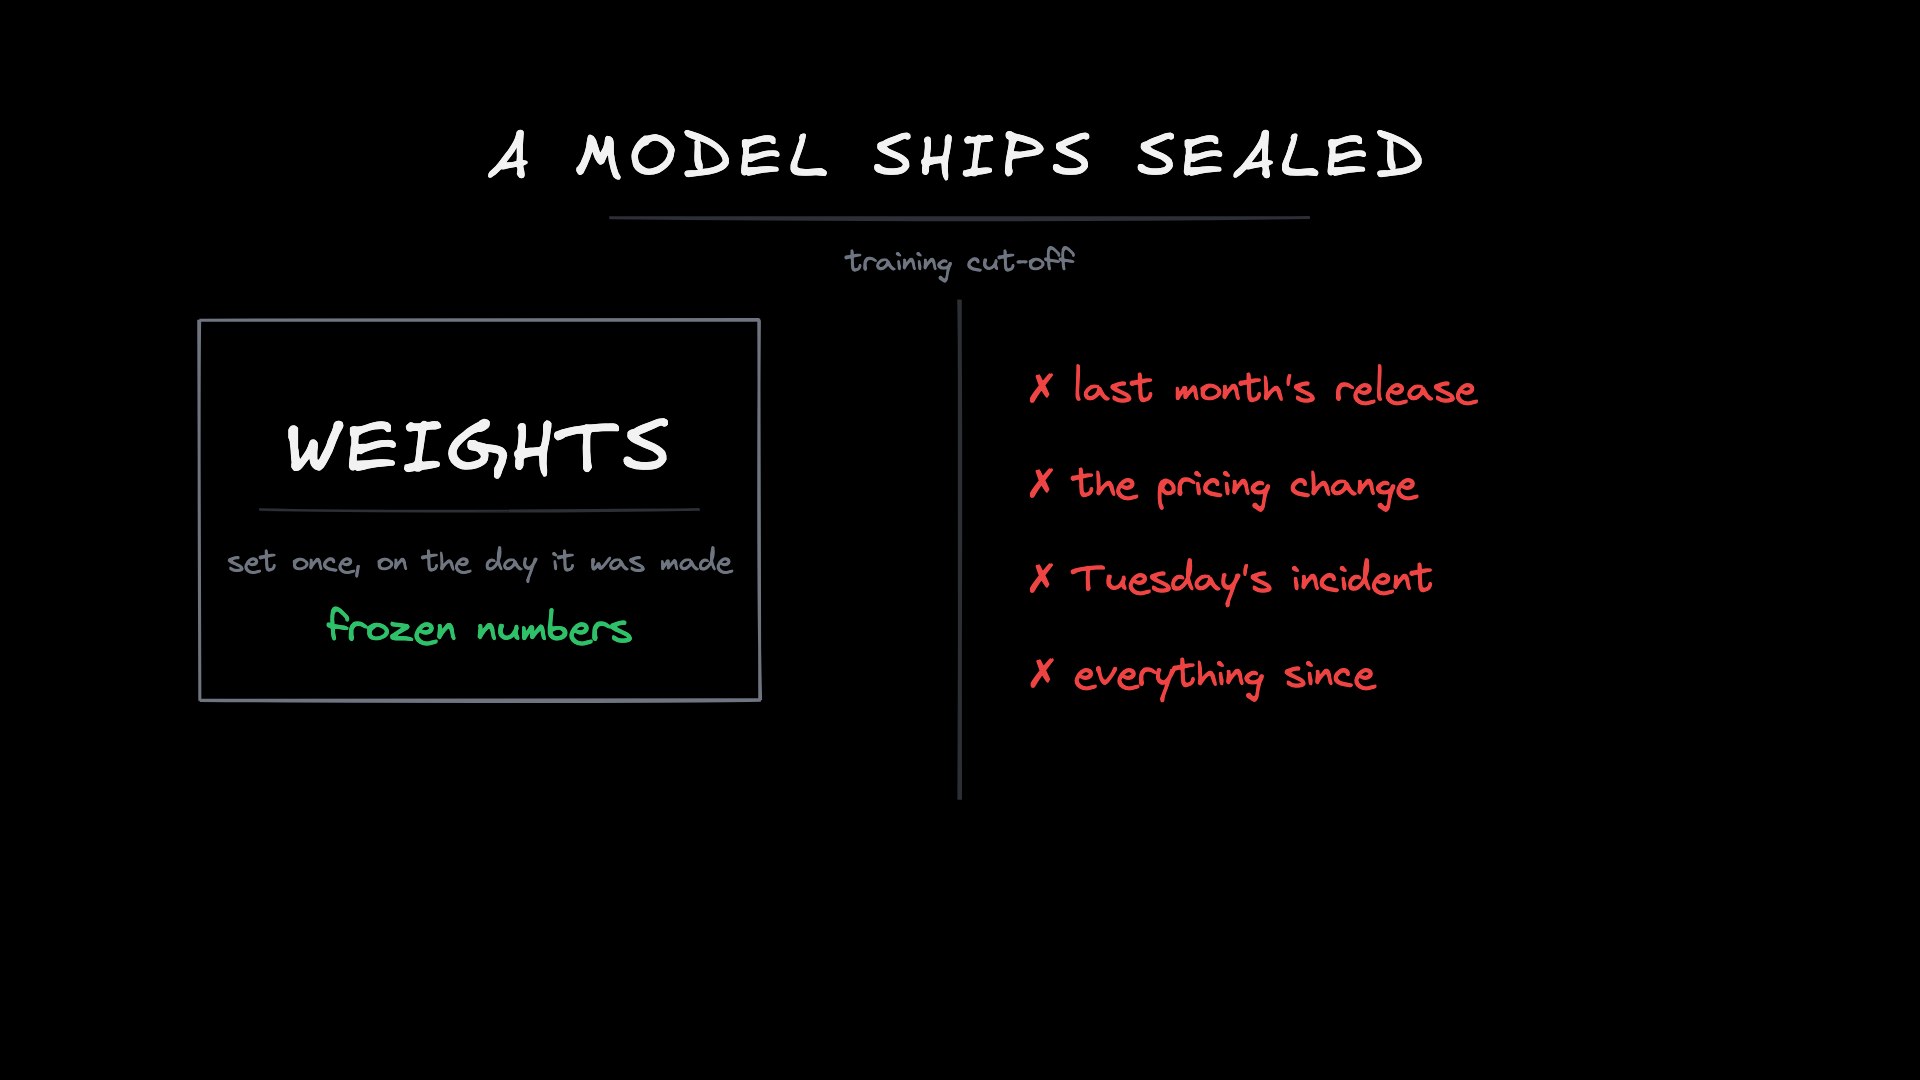
Before you start. You need Tokens & Embeddings, which turned any piece of text into a point in space, positioned so that two texts about the same thing land near each other - that nearness is the only machinery this lesson uses. Text is measured in tokens there, chunks of roughly three quarters of a word. You also need one fact from From Transformer to LLM: a model’s knowledge is baked into its dials during training and does not change afterwards.