Prefix Caching (the same start, computed once)
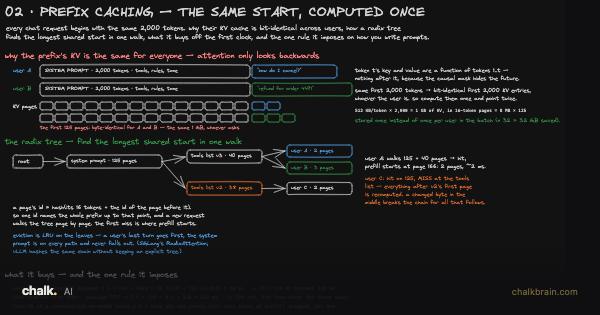
Serving LLMs. Follows “The Two Clocks” (The Two Clocks (TTFT, TPOT, and why goodput is the number)), which put a name on the wait before a reply’s first word. This board takes that wait’s biggest fixed cost apart: the standing instructions every message to a chat product starts with, and the trick that pays for reading them only once.
Before you start. A model reads and writes in tokens: word-pieces, a few characters each, so “cancelling” might reach it as two of them. While it reads, it writes notes about every token it has already seen, so it never has to read those tokens again - that pile of notes is the KV cache from Inference (sampling, context, KV cache, hallucination). From The Two Clocks (TTFT, TPOT, and why goodput is the number) you need TTFT, time to first token: the wait before a reply’s first word, which is mostly one read of the whole prompt, called prefill.