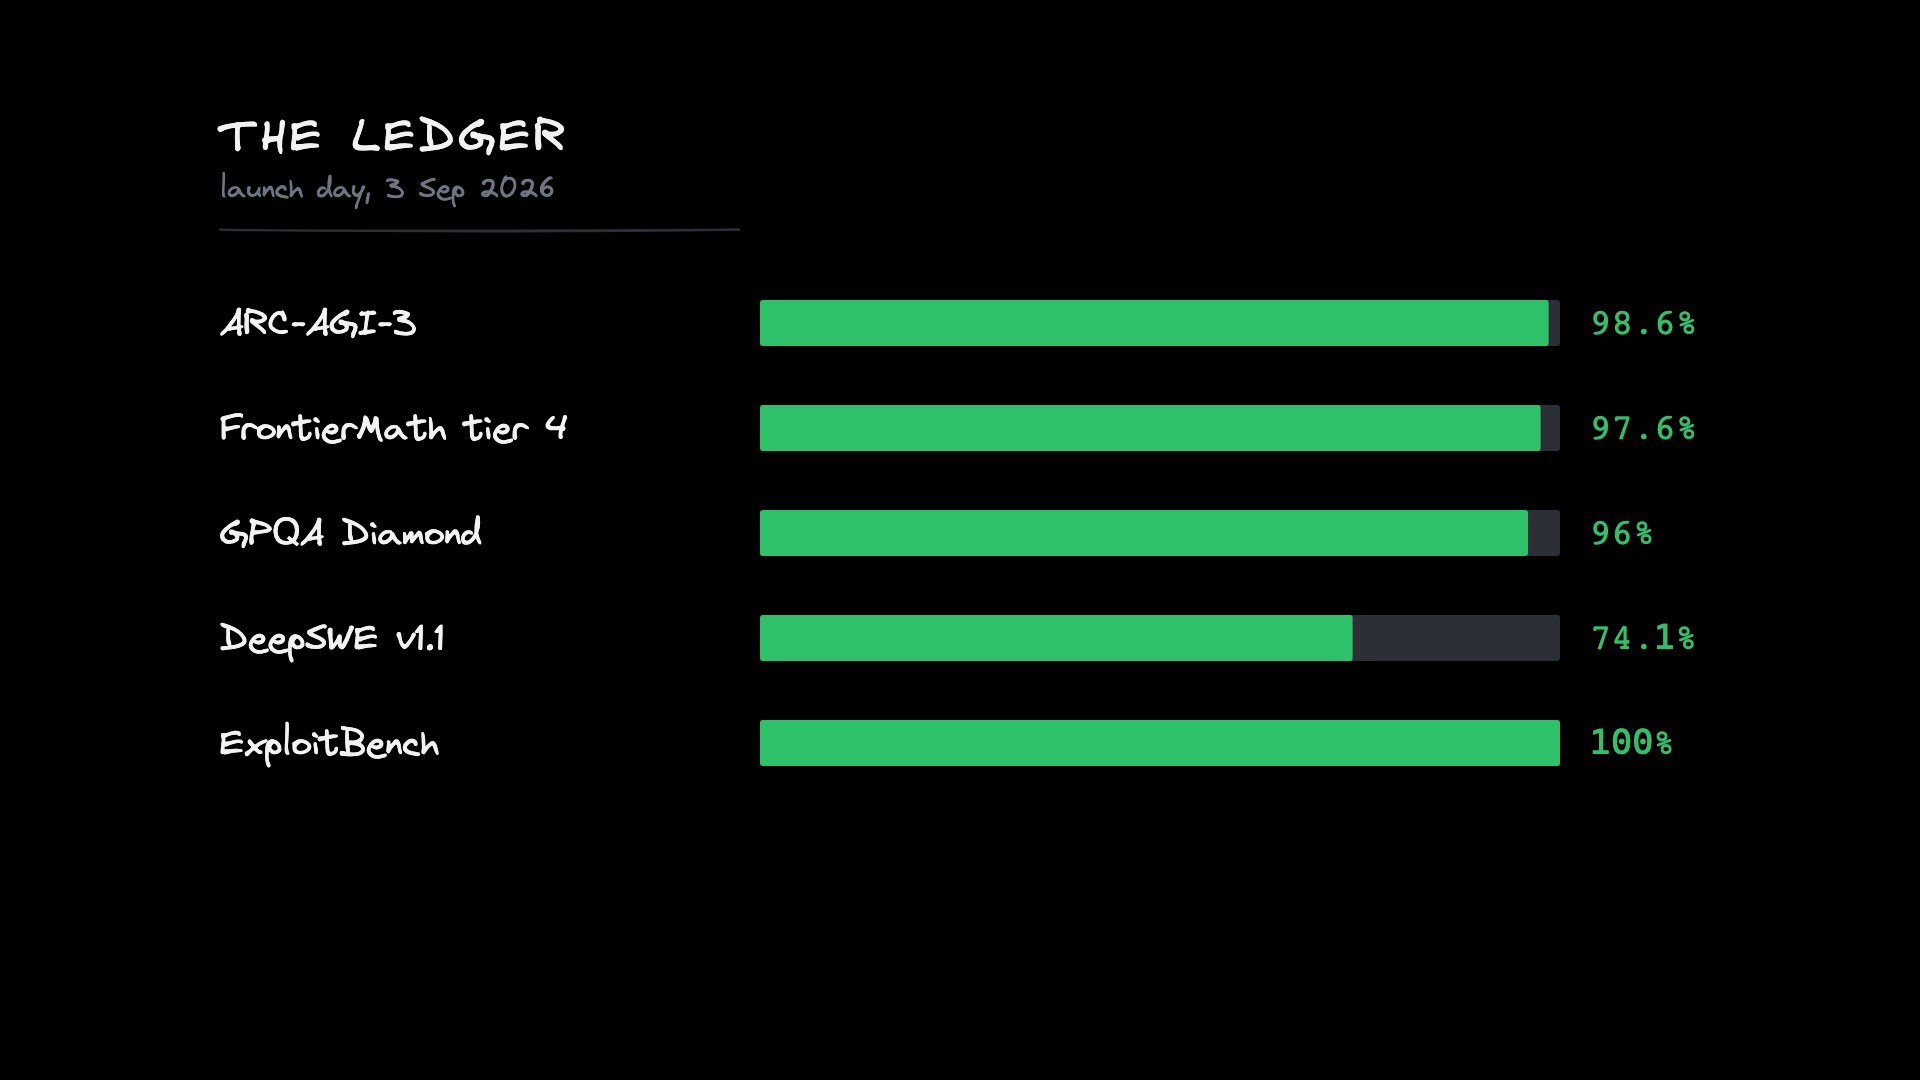
Reasoning & Test-Time Compute (why “thinking longer” works)
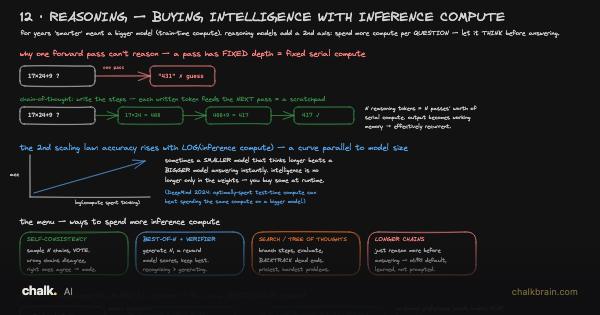
The Reasoning and Test-Time Compute board on the How LLMs Work track. This lesson tells how the frontier was found by adding one sentence to a prompt, and by the end you will know what you buy when you turn “thinking” up.
Before you start. Three words from earlier lessons. Layers are the rows a model is built from, and it has a fixed number of them. Dials are the adjustable numbers those rows hold. Training is the one pass, long finished before you ask anything, that set them. To answer, the model runs every layer once to make one word, feeds that word back in, and runs them all again for the next. That is the slow half of serving, from Inference at Scale (why an LLM is fast, and cheap), and it sets this lesson’s three costs: 7 milliseconds a word on a chip you have to yourself, 39 milliseconds when 32 people share it, and 80 cents per million words of output.