Four Ways to Split a Model
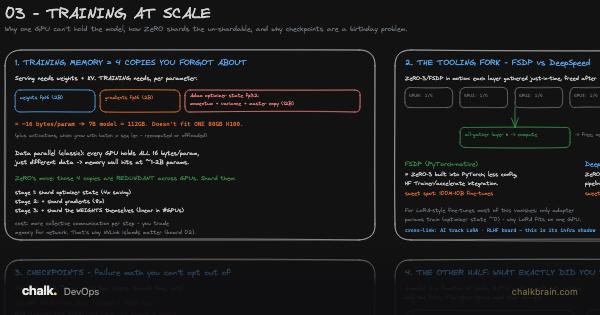
The Training at Scale board draws why one GPU cannot hold a model in training, and how the work gets cut up.
Before you start. From The GPU (thousands of cores, and the memory that feeds them): a GPU is thousands of simple calculators with memory that is very fast but small, 80 GB on an A100. From What a Neural Network Is: a weight is one adjustable number inside the network, a dial, and a model’s size is how many weights it has. From How It Learns (loss, gradient descent, backprop): training shows the model examples, measures how wrong it was, and nudges every weight a little; the list of which-way-to-nudge numbers, one per weight, is the gradient. From Why the Loss Won't Go Down: Adam, the standard way to take those nudges, remembers two extra numbers for every weight. A number can be stored in 4 bytes (careful) or 2 bytes (half the room, a little rougher).