Index

Module 02 · AIFrom a model to an app

The Maths Floor, Part 2: Probability, Softmax and Temperature
Inference
Inference · Open board

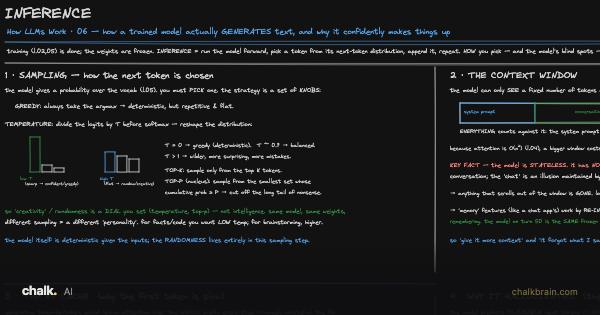
The Inference board of the How LLMs Work track. Its first section, sampling, says “divide the logits by T before softmax”. This lesson is the arithmetic under that one line.

Before you start. Vectors, Dot Products and Matrix Multiply showed that a layer is a row of dot products, so the model’s last layer hands back one plain number, a score, for every word it could say next. From Transformer to LLM is where that last layer comes from: a machine trained to fill in the next blank, one word at a time. Inference (sampling, context, KV cache, hallucination) is where this lesson is used: the model draws its next word at random, with a dial on how random. Here you learn what the draw and the dial actually compute. Adding, dividing, and one button on a calculator.

Continue reading with a plan

The first three lessons of every track are free. This lesson is included with a plan, which unlocks every lesson, board, video, lab and paper for one price.

View plans →Already a member? Sign in

Lab

One GPU, one chat, cores 99% idle. How many more chats fit before anything gets slower?

Drag Chats sharing one read of the weights to the right and watch operations per byte rise until The wall stops it.

Open The batch size dial →

The model has read 'The weather today is'. How often does it say something other than sunny?

Drag How hard the drum is shaken from T = 0.1 to 5 and watch Outside the top word climb.

Open The temperature dial →

Review AI →

Saved in this browser, and to your account when you sign in.