Routing and Cascades (not every request needs the big model)
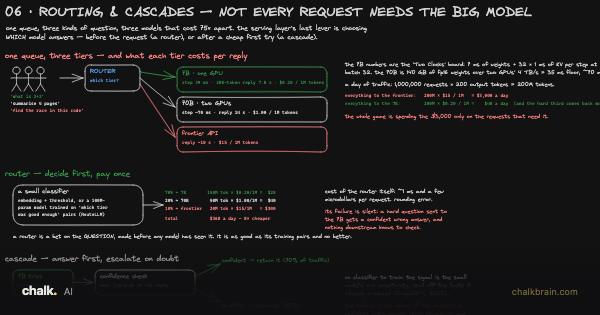
The last board of the Serving LLMs run. Five earlier boards each made one fixed-size model faster: The Two Clocks (TTFT, TPOT, and why goodput is the number) measured its two clocks, Prefix Caching (the same start, computed once) and Chunked Prefill (one long prompt must not freeze the room) fixed the first and second, Prefill / Decode Split (two pools, one KV in flight) split the pool in two, Constrained Decoding (the grammar holds the pen) reached into its sampler. This board steps back to the front door and asks the question none of them asked: does this request even need that model? One queue, three price tags 75 times apart, and two different ways of deciding which one a question gets.
Before you start. A model charges you for every word it reads and every word it writes. A bigger model charges more for each of those words, and answers harder questions better. The five lessons before this one took one model of one fixed size and made its words cheaper. This lesson lets the size change too, by picking which model a question goes to.