Inference at Scale (why an LLM is fast, and cheap)
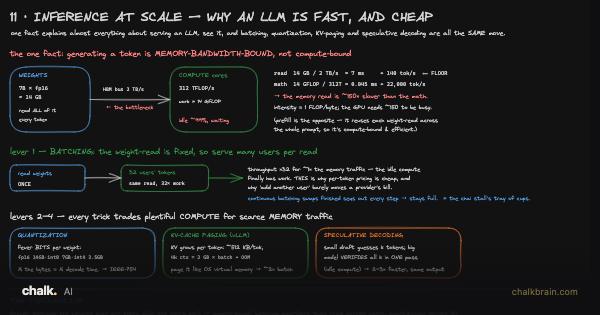
The “Inference at Scale” board of the How LLMs Work track. It draws one fact and the four tricks that fall out of it. This lesson is how people found each one, mostly by running out of money.
Before you start. From Inference (sampling, context, KV cache, hallucination): a model writes a reply one token at a time, a token being a chunk of text about three quarters of a word, running the whole model again for each one and keeping a scratch pad called the KV cache so it never re-reads the conversation from the start. Three more of its words recur here: the model’s stored numbers, its dials, are its weights; a layer is one row of those dials, and the model is a stack of rows; and the model never picks a token outright, it scores every possible next token and rolls dice weighted by those scores. That lesson explained what generation does; this one explains why it costs what it costs.